AI projects: from concept to production — fast and efficient

A sovereign AI platform for business: a model catalog, compute resources, and an environment for AI training and inference — all in one place. Start with a ready-made solution or build your own, without assembling infrastructure from scratch.

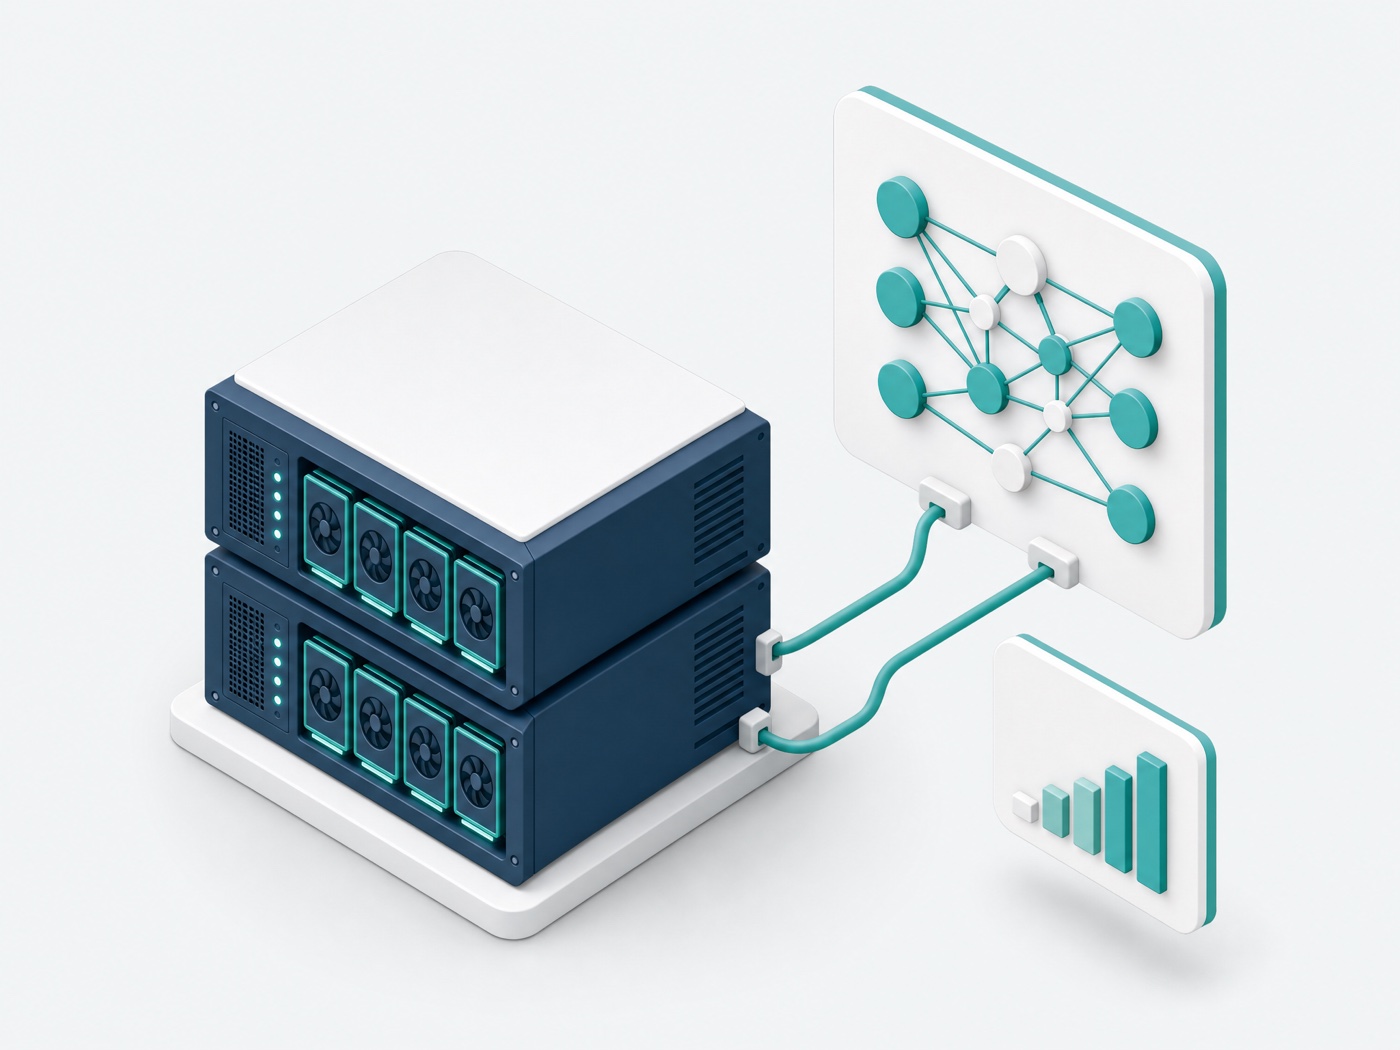
Isometric illustration: Pro-Data GPU servers connected to an AI model and a monitoring dashboard

Three steps to a single solution

Each tool does its own job and makes sense without a walkthrough of the technical architecture.

01
Available

GPU Infrastructure for AI

For teams that train models, run inference, and build AI products.

A model catalog, a Playground for experiments, and a ready-to-use API. Choose a model, test it, and connect it to your application—without setting up the infrastructure yourself.
model catalog
Playground
model deployment
inference
API
streaming
function calling
structured output
monitoring
GPU selection for deployment
The team compares several models in an hour and selects the one that fits their scenario.
02
Available

Cloud Platform

For startups that need flexible resources to launch and grow a digital product.

Jupyter, VS Code, and GPU containers with ready-to-use compute access. Create environments for developing, training, and fine-tuning models without manually configuring GPU infrastructure.
Jupyter
VS Code
GPU containers
custom Docker environments
GPU access
Python and ML frameworks
experiments
training and fine-tuning
working with your own models
Data Scientists launch Jupyter with the required environment and start training models immediately.
03
Coming soon

Bare Metal Dedicated Servers

For projects with high performance and isolation requirements.

Visual assembly of agents and workflows, ready-made templates, and integration with corporate systems. AI applications that don't just answer, but also take action.
visual agent builder
workflow
ready-made templates
integrations
tools and APIs
scenario testing
agent deployment
access management
The agent receives a client request, analyzes it, and performs actions within corporate systems.

Three ways to access GPUs

From a flexible pool for experiments to fully isolated infrastructure built to your requirements.

Format 01

On-demand

Availability
As resources become available
Payment
For actual time used
Resource isolation
Shared pool
Launch
Immediately
GPU allocation per project
Full map
Experiments, training, and tasks without constant load.
Format 02

Dedicated

Availability
Guaranteed
Payment
For the reservation period
Resource isolation
Dedicated cluster
Launch
Upon request
GPU allocation per project
Map segment
Production workloads with predictable traffic.
Format 03

On-Premise

Availability
Guaranteed
Payment
Custom
Resource isolation
Physical, full
Launch
Upon request
GPU allocation per project
Map segment
Banking, fintech, public sector — data residency.

Your data physically stays within the country

This is not an option for a specific format, but a core characteristic of the entire platform — regardless of whether you use a shared pool or a dedicated cluster.

Physical presence in the region

Data centers in Uzbekistan and Kazakhstan — your data doesn't cross the border and isn't processed on infrastructure in other jurisdictions.

Regulatory compliance

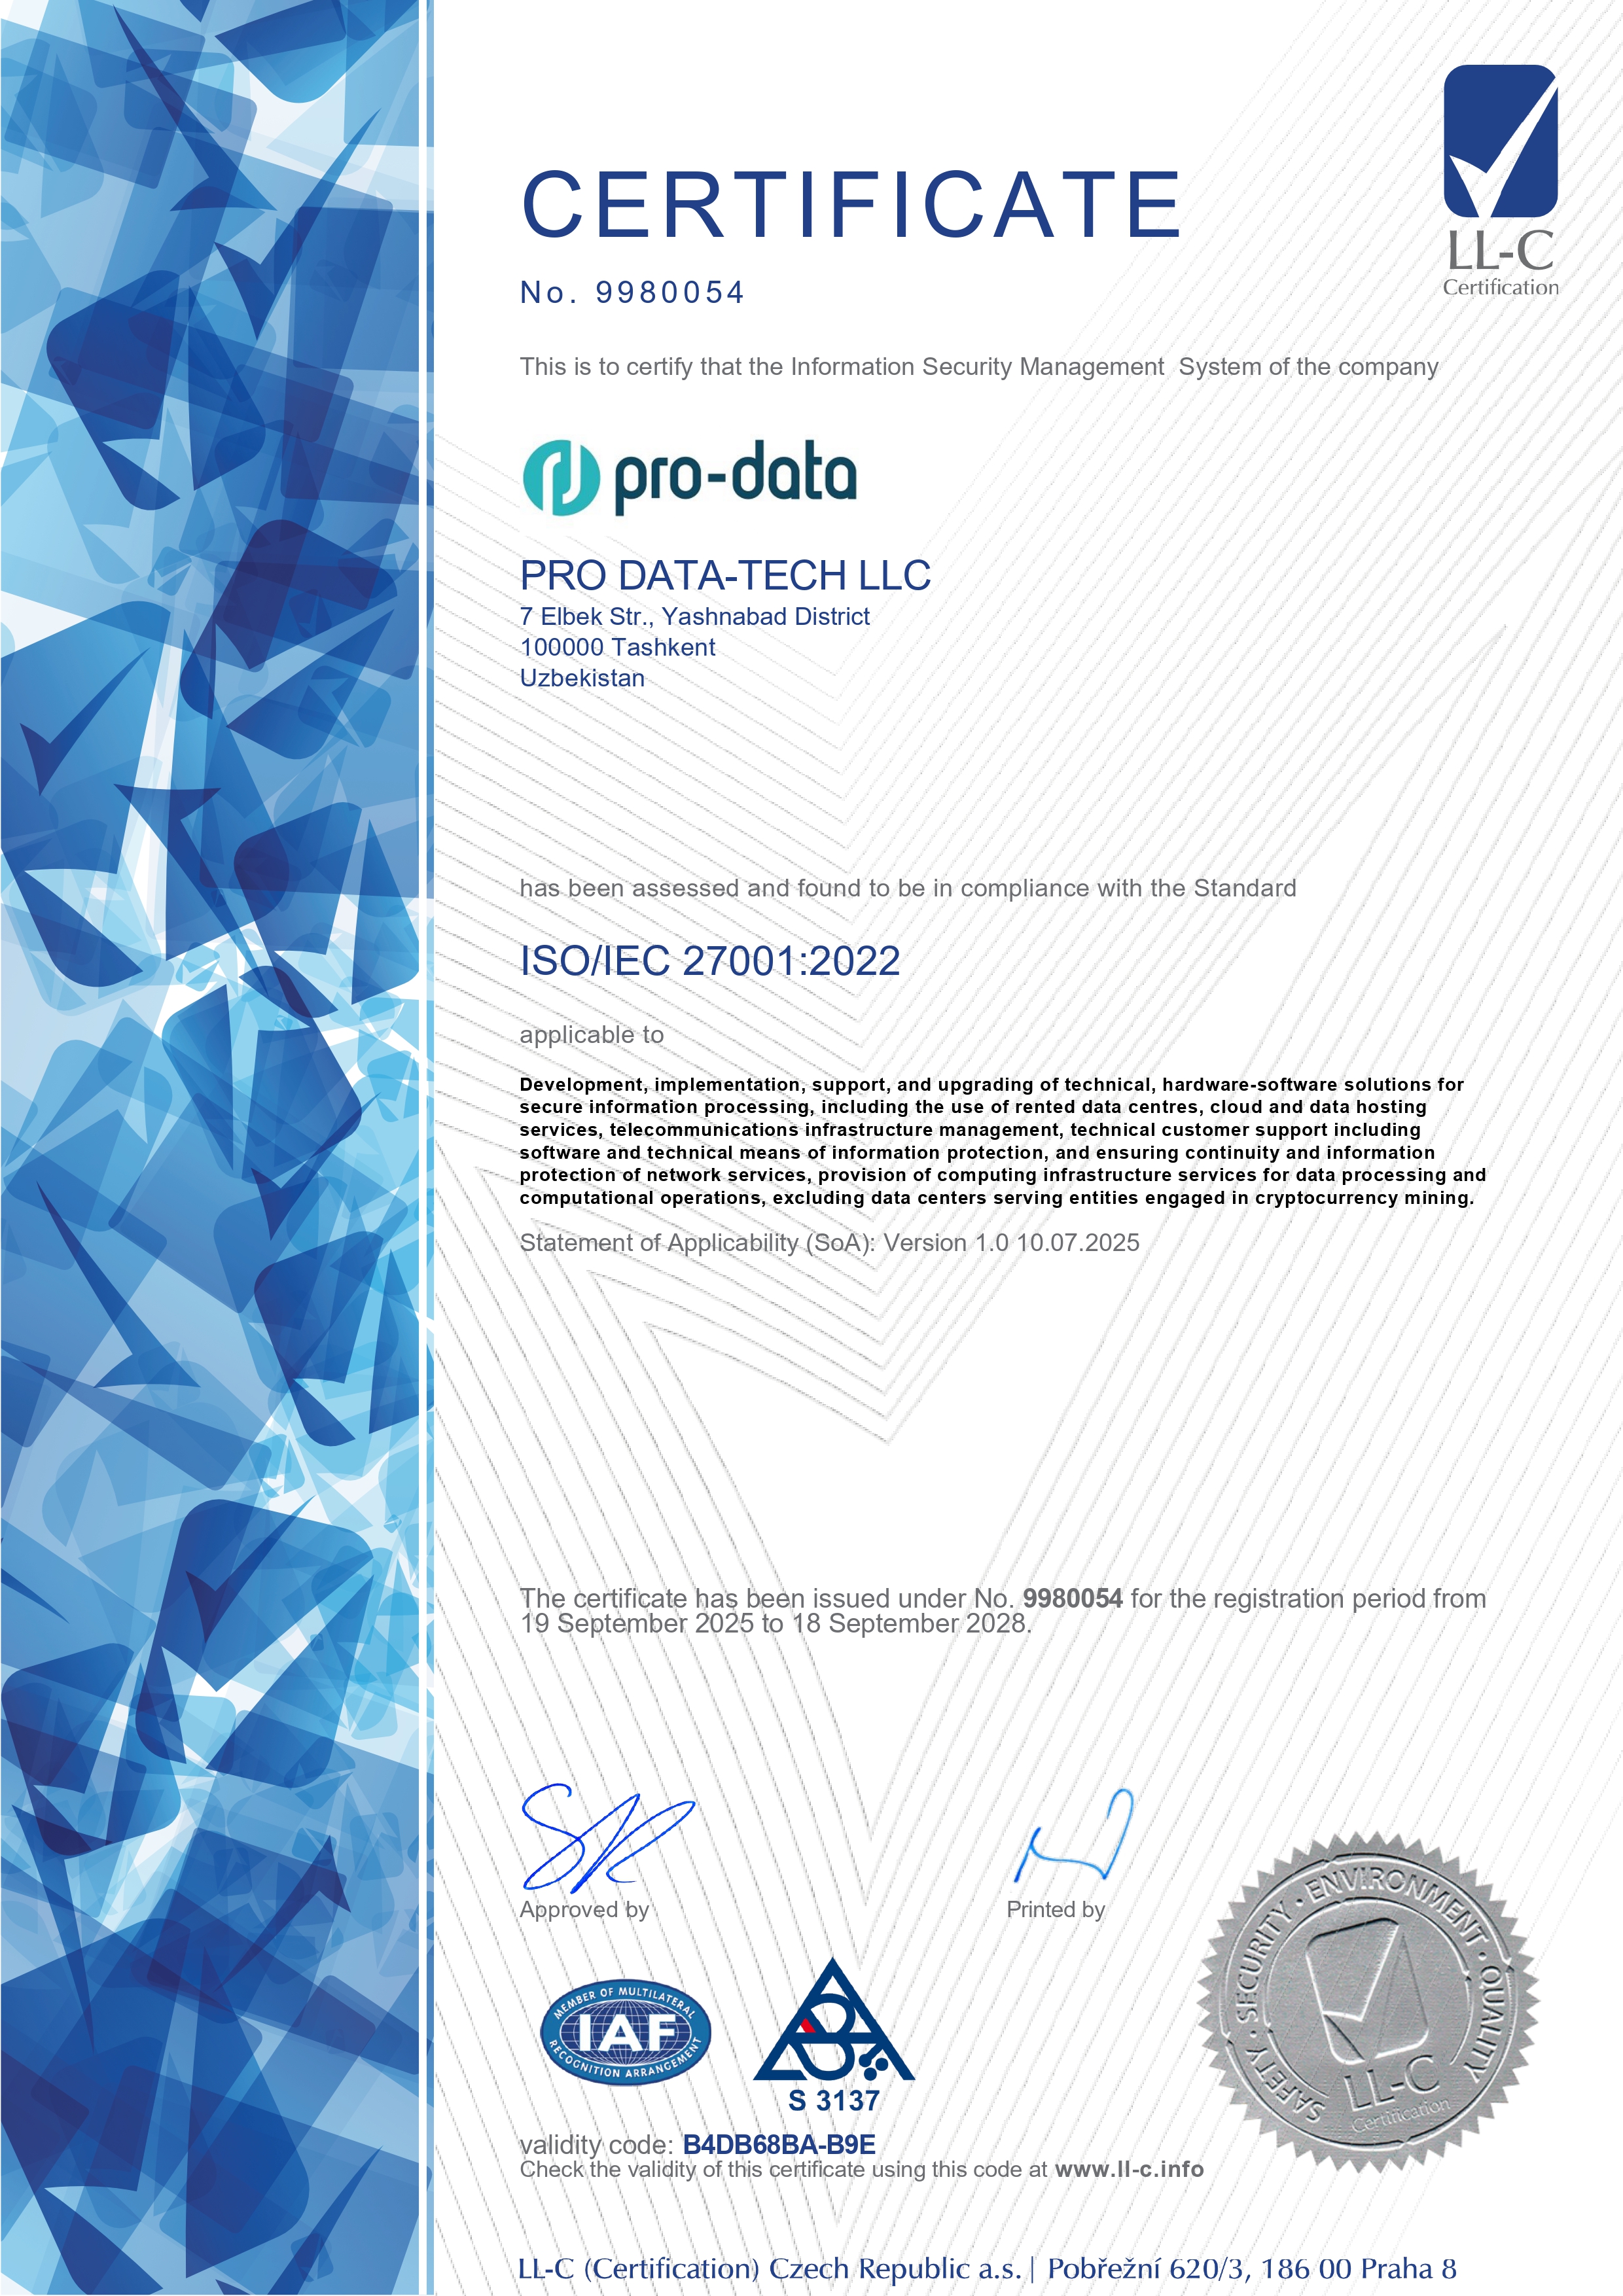
Our infrastructure and processes meet data storage and processing requirements, including local regulations.

Minimal latency

With servers located inside the country, traffic doesn't travel through foreign nodes. That means low ping, instant service response, and consistently high data transfer speeds for your users.

Platform components work across all three products

Unified infrastructure, access, and billing, regardless of which tool you are using.

GPU infrastructure
Project-based isolation
Networking
Users & Roles
API
Monitoring
Security & Access Control
Storage
Based on Technology

Results and benefits

Customer communication

Technical support, onboarding, and knowledge base search — the model answers based on your data, not general internet knowledge.

Document processing

Data extraction from invoices and contracts, request classification, and summarization of large volumes of text.

Development assistance

Code generation, refactoring, and automated testing on dedicated infrastructure, with no risk of corporate code leaks.

Voice stream processing

Real-time speech recognition for call centers, call transcription, sentiment analysis, and automated meeting minutes.

Banking scoring

Credit scoring and risk analysis models using data that never leaves the bank's perimeter — critical when handling financial information.

Batch processing during off-peak hours

Mass data processing, model retraining, and analytics at night or during off-peak hours—so your rented GPUs don't sit idle but work at full value.

Talk to us about the platform

We'll go through your use case and find the right setup — from a quick model test to a dedicated cluster on your own site.

Submit a request
×

Request a Consultation

We'll go through your use case and find the right GPU access format for your workload.

Thank you! Your application has been sent – we'll get in touch with you shortly.
Oops! Something went wrong. Please try again or email us.

Frequently Asked Questions

Didn't find an answer? Write to us – we'll help you sort it out.

Do we need our own team of ML engineers?
No. Inference Studio gives you ready-to-use models via API, with no in-house expertise required. For deeper development, there's AI Lab — tools ML engineers already know how to work with.
How is pricing calculated?
Pricing depends on the GPU access model you choose and the volume of resources you use. We'll walk you through the details and size a configuration for your use case during a consultation.
Will our data really stay within the country?
Yes — the infrastructure is physically located in the region. For maximum control, an On-Premise option is available: on our isolated infrastructure or at your own site.
What if there's no free capacity in the On-Demand pool?
For workloads with constant load, we recommend Dedicated — it guarantees capacity availability. On-Demand suits flexible workloads that aren't time-critical.
Can we build AI agents right now?
Agent Studio is in development. For now, agent workflows can be assembled manually via the Inference Studio API.